Documentation / Comparison
Comparison
Verifpal searches for attacks within explicit limits. ProVerif and Tamarin can prove properties for unbounded sessions. Their languages, automation and demands on the model author differ.
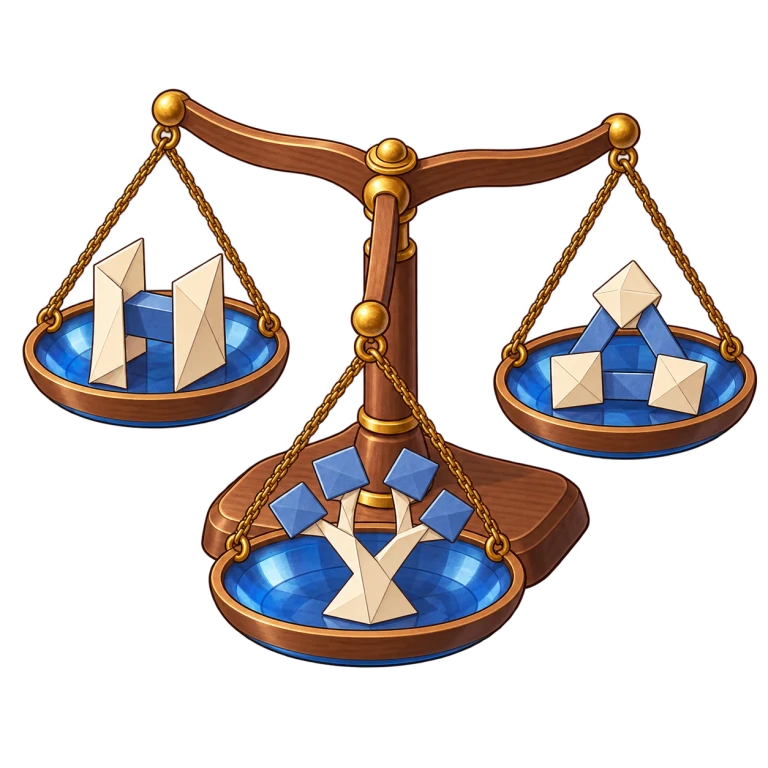
The tradeoff triangle
For sufficiently expressive symbolic protocol models, secrecy with unbounded sessions and fresh nonces is undecidable. A general algorithm cannot promise all three: coverage of arbitrarily many sessions, termination on every input, and an exact yes/no answer every time. Durgin et al. establish the undecidability result and several decidable restrictions.
No general algorithm
guarantees all three.
ProVerif does not always terminate. Verifpal’s heuristic search can miss attacks even at the selected session count, so it is incomplete within that bound. The existence of decidable bounded-session problems does not make Verifpal a complete decision procedure. Its research paper documents the proposal families and depth restrictions that shape the search.
How the tools work
ProVerif: prove through abstraction
ProVerif translates processes into Horn clauses, an abstraction that makes unbounded reasoning tractable in many cases. Ordinary Horn facts are reusable: recording that a message can occur does not count how often it was emitted, and the clauses retain only part of each participant’s state. A clause can be applied repeatedly even where a concrete session executes that step only once. A derivation can therefore combine steps that no actual execution can perform together. Blanchet’s account of the abstraction explains how ignoring repetitions enables unbounded analysis while admitting false attack derivations.
Resolution derives the consequences of those clauses. If the secret is not derivable even in this more permissive model, it is secret in the protocol. If it is derivable, ProVerif attempts to reconstruct an execution. An unsuccessful reconstruction can produce cannot be proved, which means inconclusive, not insecure. Its output guide distinguishes proofs, reconstructed attacks and inconclusive results.
ProVerif has no general termination guarantee, though one holds for the tagged-protocol class studied by Blanchet and Podelski. On harder models, lemmas, induction and other refinements can improve precision and help the analysis finish. These features may require additional work on the model.
A concrete example: symmetric-key Needham–Schroeder. The Verifpal paper’s comparison artifact records the following ProVerif 2.05 output for Bob-to-Alice authentication. The reconstruction fails at an input where its derivation attempts to reconcile different ciphertexts in the same session:
Try adding a [precise] option on it.
Trying with the initial derivation tree instead.
Could not find a trace corresponding to this derivation.
RESULT inj-event(AliceAcceptsFromBob(x)) ==> inj-event(BobSendsToAlice(x)) cannot be proved.
RESULT (even event(AliceAcceptsFromBob(x)) ==> event(BobSendsToAlice(x)) cannot be proved.)
The [precise] option can help recover information lost in the abstraction. The same artifact records attack findings for the corresponding direction of authentication in Tamarin and Verifpal:
| Tool | Query or lemma | Recorded result |
|---|---|---|
| ProVerif 2.05 | Alice’s acceptance corresponds to Bob’s send, with and without injectivity | cannot be proved |
| Tamarin 1.12.0 | auth_bob_to_alice |
falsified - found trace (7 steps) |
| Verifpal 1.4.2 | authentication? Bob -> Alice: e_n_b |
Fail, with a trace replacing e_n_b with nil |
The models use different acceptance conditions. Tamarin checks a non-injective event correspondence after matching a ciphertext; Verifpal’s reported attack reaches an unchecked decryption. These results therefore concern different queries and attacks. The raw evidence is in bench/outputs/needham-schroeder.{proverif,tamarin,verifpal}.txt in the paper’s artifact.
Tamarin: prove by solving constraints
Tamarin models protocol state with multiset rewriting rules and searches for executions satisfying or violating a property. Its trace analysis can establish unbounded proofs or construct counterexamples under its supported theories. Search may continue indefinitely: an obligation can generate another obligation of the same shape at an earlier point in an execution. The Tamarin manual explains both its automatic and interactive modes.
The analyst can supply induction, lemmas about where messages originate, reusable invariants, and heuristics that guide the search. Tamarin’s property language and proof controls provide considerable flexibility. Many models run automatically; difficult ones can require substantial expertise. Its explicit state and built-in algebra for Diffie–Hellman, XOR and pairings make it especially valuable when those details matter.
A helper lemma for Needham–Schroeder–Lowe. The comparison artifact’s untyped Needham–Schroeder–Lowe model uses a hand-written types [sources, reuse] lemma to close message-origin cases left unresolved by --auto-sources in that encoding. It follows Tamarin’s own untagged NSLPK3 example. Here is the complete lemma from the artifact’s models/tamarin/nsl-pk.spthy:
lemma types [sources, reuse]:
    "(All na m1 #i. IN_B_1_na(na, m1) @ #i ==>
        ((Ex #j. KU(na) @ #j & #j < #i) |
         (Ex #j. OUT_A_1(m1) @ #j & #j < #i)))
     &
     (All nb m2 #i. IN_A_2_nb(nb, m2) @ #i ==>
        ((Ex #j. KU(nb) @ #j & #j < #i) |
         (Ex #j. OUT_B_1(m2) @ #j & #j < #i)))"
The first half says that a nonce Bob receives either was already known to the attacker or came in an earlier first message from Alice. The second states the analogous origin condition for Alice’s received nonce. The sources annotation makes the lemma available to refine the origin analysis; reuse makes the proved result available to subsequent lemmas. The remaining proofs can then use this fact.
Automatic source generation reduces this burden on many examples. It does not guarantee a finished proof: Cortier et al.’s evaluation lists untagged NSLPK3 as needing an additional reuse annotation, and the manual requires checking both the generated lemma and whether it resolves the outstanding cases.
Verifpal: search within explicit limits
Verifpal combines a fixed primitive vocabulary, a finite session expansion and bounded term construction with backward search from the security question. Every candidate attack runs as one execution of the whole model, in which a substituted value is delivered only when the attacker can derive it from what that execution has already disclosed. Only a query violation found in such an execution is reported. The analyst supplies the protocol and queries, without helper lemmas or proof strategies. The analysis guide describes the execution and the search.
The search terminates, though it can take a long time. Finishing the search does not prove security. Each report includes the assumptions, search limits and any attacks found.
Working with Verifpal
A small modeling language
A model describes what each principal knows, generates, computes and sends. Five query forms check confidentiality, authentication, freshness, equality and linkability. The language follows the order of the protocol’s messages and computations.
The 25 primitives have fixed rules, so model authors do not need to write equations for them. You still need to check that those rules represent the cryptography your protocol uses. Tamarin also offers built-in theories; Verifpal requires its fixed set and does not support custom equations.
Explicit assumptions
Guards specify authentic delivery, and checked operations stop a participant on failure. Phases specify when keys are compromised; scenarios vary the peers; primitive annotations weaken cryptographic operations. Change these assumptions to test an unauthenticated key, a malicious peer or a later key leak.
// Fragment: Bob receives an authenticated key and checks the proof.
Alice -> Bob: [pk], proof
principal Bob[
	_ = SIGNVERIF(pk, challenge, proof)?
]
In the quickstart’s complete model, removing the brackets lets the attacker substitute its own key and signature. Removing ? lets Bob continue after a failed check. These changes show why Bob needs both an authenticated key and a signature check.
Interactions between runs
The default expands each principal into two sessions that share long-term keys but generate distinct fresh values. The attacker can carry messages between those runs; peer scenarios also vary who the participants believe they are talking to. This can find attacks that need several runs. The research paper demonstrates Lowe’s Needham–Schroeder relay, the FFGG rotation and attacks involving later key compromise.
Reading a finding
Verifpal describes observations, constructions, substituted messages and checks using the names from the model. Session and scenario suffixes distinguish repeated runs. The trace shows which key was trusted, which value was replaced and why the recipient accepted it.
Compare each trace with the real protocol. For example, if an attack requires reading a value that the implementation encrypts, the model may need correction.
Development tools
The Workbench runs locally in a browser. Verifpal also provides editor diagnostics, shareable models, structured reports and command-line checks. You can keep models and expected results alongside the implementation and check them as the design changes.
Effort required for unbounded proofs
ProVerif and Tamarin can prove properties beyond Verifpal’s search bounds. The following studies show the modeling work and computing resources that some large proofs required.
TLS 1.3 with Tamarin
Cremers et al.’s comprehensive analysis reports approximately three months of modeling work, most of it spent writing lemmas that divide the proof into manageable parts. With those lemmas, proving the entire model took about a week of work. Loading the model required over 10 GB of RAM, and a proof could consume 100 GB. Checking the completed proofs took about a day and still required substantial memory. The authors describe the manual guidance as part of constructing the proof, rather than merely running a verifier. A Comprehensive Symbolic Analysis of TLS 1.3, CCS 2017, §5.1.1.
5G authentication with Tamarin
Basin et al.’s protocol model occupies roughly 500 lines. Its analysis uses 124 lemmas occupying about another 1,000 lines: helper lemmas, sanity checks and security claims, including variants that test which assumptions are necessary. Dedicated proof strategies add roughly 1,000 lines of Python; developing those strategies took several person-months. With that infrastructure in place, Tamarin established the proofs and found the attacks in about five hours.
The authors report that fully automatic mode without their proof strategies failed to establish relevant security properties and even full protocol executability. A Formal Analysis of 5G Authentication, CCS 2018, §§4.4.2–4.4.3.
TLS 1.3 and TLS 1.2 with ProVerif
Bhargavan, Blanchet and Kobeissi report that their individual TLS 1.3 and TLS 1.2 models verified in seconds, while composing them took several minutes. Adding features and modes increased both runtime and memory use; their scaling discussion reports hours on a powerful workstation for the final model combining all modes. Verified Models and Reference Implementations for the TLS 1.3 Standard Candidate, S&P 2017, §III.
The paper’s development summary separately reports 1,030 lines of ProVerif, about 70 minutes to complete its proof suite, and approximately three person-weeks for a ProVerif expert to develop the models. Development effort, §VIII.
These historical studies are not benchmarks against Verifpal or estimates of typical runtime. They established stronger guarantees than bounded search, and both tools can complete simpler analyses automatically. The studies also contributed to standards while those standards were being designed.
Verifpal lets a team search for design mistakes without undertaking a proof development of this scale. A project that needs an unbounded proof will still need a tool that can provide one.
What the results establish
All three tools depend on the model’s algebra, attacker capabilities and security properties, and on how accurately the model describes the protocol. A proof about a model that stops on an invalid signature does not cover code that continues. For an accurate model, an unbounded proof rules out attacks that Verifpal’s search may not have explored.
PASS [search exhausted at 2 sessions]- The search found no contradiction at that session count, and no proposal exceeded the depth limit. The search can still miss attacks at two sessions because it does not try every possible construction or interaction. Increasing the count adds runs. Result codes that match at successive counts do not prove that higher counts will agree.
PASS [search truncated: term depth]- No contradiction was found among the explored proposals, and a depth limit excluded at least one candidate. Preserve this qualification when reporting the result.
FAIL- Verifpal found one execution of the model that violates the query. Every substitution in it was derivable from what the execution had disclosed before its delivery, and the trace narrates that execution after removing substitutions it did not need. It is not a machine-checkable certificate, and it describes the model rather than an implementation.
The results reference gives the full scope. Keep the model, version, assumptions, bounds and qualifiers with any finding. Reproduce the behavior against the implementation when making a claim about a deployed system.
Queries with similar names may test different properties. Verifpal’s equivalence? compares resolved values; it does not establish observational equivalence. Its unlinkability? searches for a concrete link witness, rather than proving that two executions are indistinguishable. Its use-based authentication checks are not interchangeable with arbitrary completion correspondences. ProVerif and Tamarin support richer properties, including equivalence analyses whose sufficient conditions can themselves be stronger than the privacy property you intended. See the ProVerif property guide and Tamarin’s equivalence documentation.
At a glance
| Dimension | Verifpal | ProVerif | Tamarin |
|---|---|---|---|
| Session scope | Explicit bound; two per principal by default | Unbounded analysis | Unbounded analysis |
| No attack reported | No contradiction found by the implemented search | May be a proof, an inconclusive result, or unfinished search | A completed trace proof establishes the property; search may remain unfinished |
| Termination | Finite search; runtime can still grow substantially | Guaranteed for specified classes, not in general | Not guaranteed in general |
| Analyst input | Protocol, assumptions and five query forms; no helper lemmas | Processes and queries; refinements or lemmas where needed | Rules or processes and properties; proof guidance where needed |
| Cryptographic theory | Fixed 25 primitives; no custom equations | User-defined operations and supported equations | Built-in and supported user-defined theories, including DH, XOR and pairings |
| Privacy as indistinguishability | Not provided by its equality or link-witness queries | Equivalence reasoning, notably diff-equivalence | Equivalence reasoning through bi-systems |
| Inspecting a finding | Numbered explanation of one execution, in model vocabulary | Derivations and reconstructed attack traces | Constraint exploration and attack graphs |
Choosing a tool
Choose a tool that can represent the protocol’s cryptographic operations and the property you need to check. Omitting an algebraic rule that an attack depends on can hide the attack.
- Choose Verifpal for bounded attack search and design review when its fixed primitives and queries fit the protocol. Its small language helps protocol authors read and review the models themselves.
- Choose ProVerif when you need automated unbounded proofs and your protocol, equations and properties fit its process model and abstraction. Be prepared to investigate inconclusive results or refine difficult models.
- Choose Tamarin when explicit mutable state, richer algebra or flexible temporal properties are central, and you need unbounded reasoning with the option to guide proofs interactively.
You can use more than one tool. A Verifpal model can help find mistakes and clarify assumptions before you develop a proof in another tool. When translating a model, check that the attacker assumptions and security properties still match. Matching verdict labels alone do not establish this.